NVIDIABlackwell Ultra
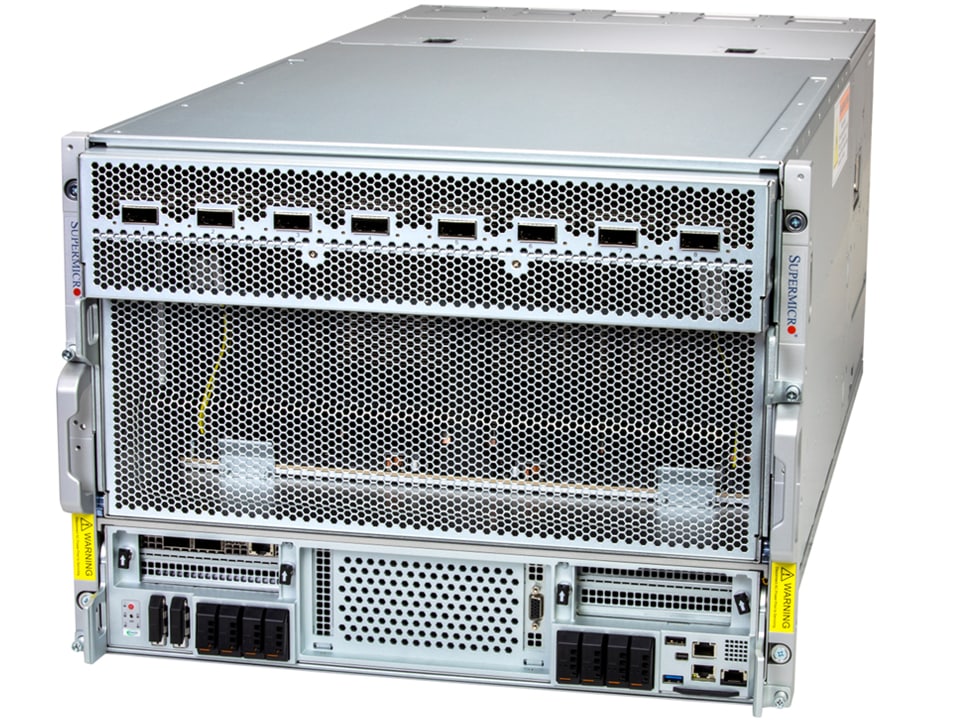
HGX B300 · 8 GPU
Eight Blackwell Ultra GPUs with NVLink 5 Switch. Configuration and cooling are agreed with the server manufacturer.
- Accelerator memory
- 2,160 GB
- Architecture and software
- SXM6 · NVLink 5 SwitchCUDA
from $634,046
 OMNAR
GPU servers for businesses in Kazakhstan.
NVIDIA HGX / NVL · AMD Instinct · Huawei Ascend
Purchase, rental and deployment planning.
Compare platforms and find the right configuration for your workload.
Eight Blackwell Ultra GPUs with NVLink 5 Switch. Configuration and cooling are agreed with the server manufacturer.
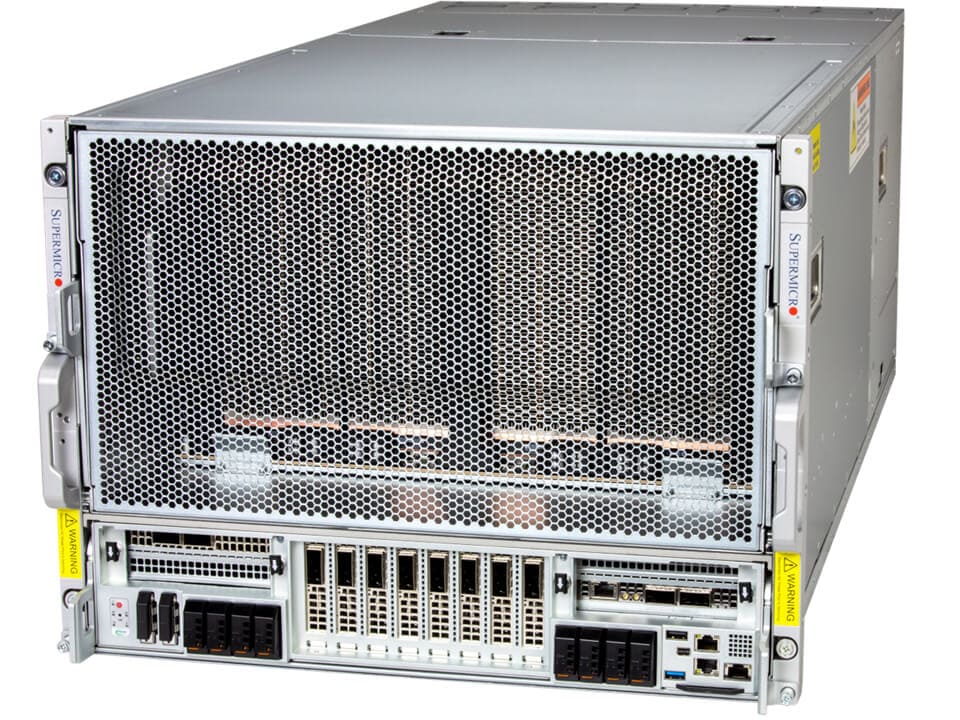
Eight Blackwell GPUs in one NVLink domain. The server and cooling are selected for the infrastructure.
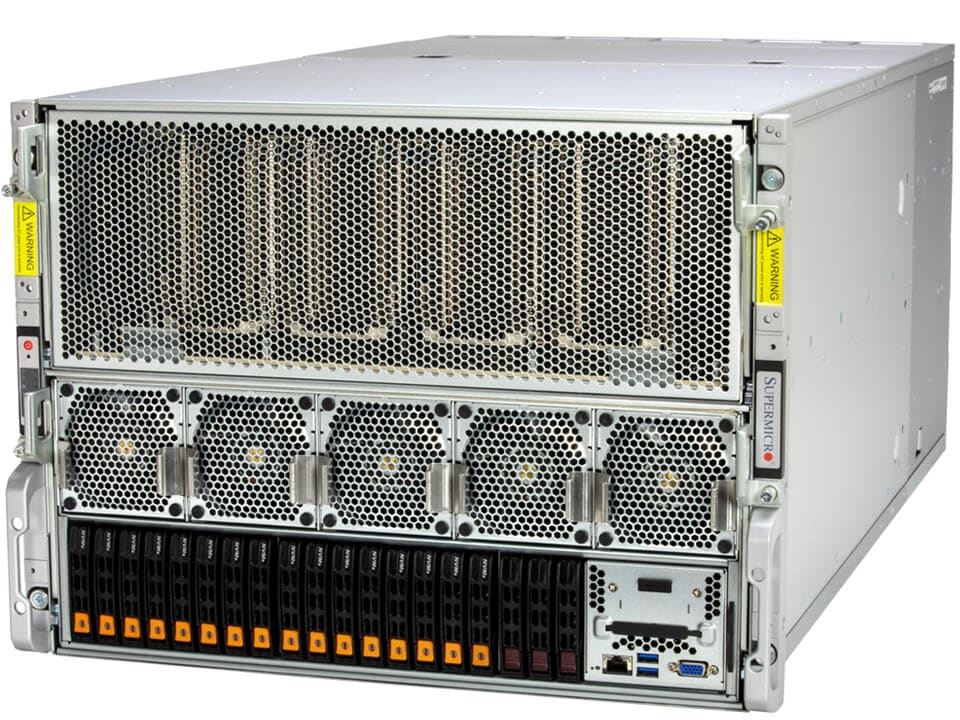
Training and inference across eight accelerators with high-speed interconnects.
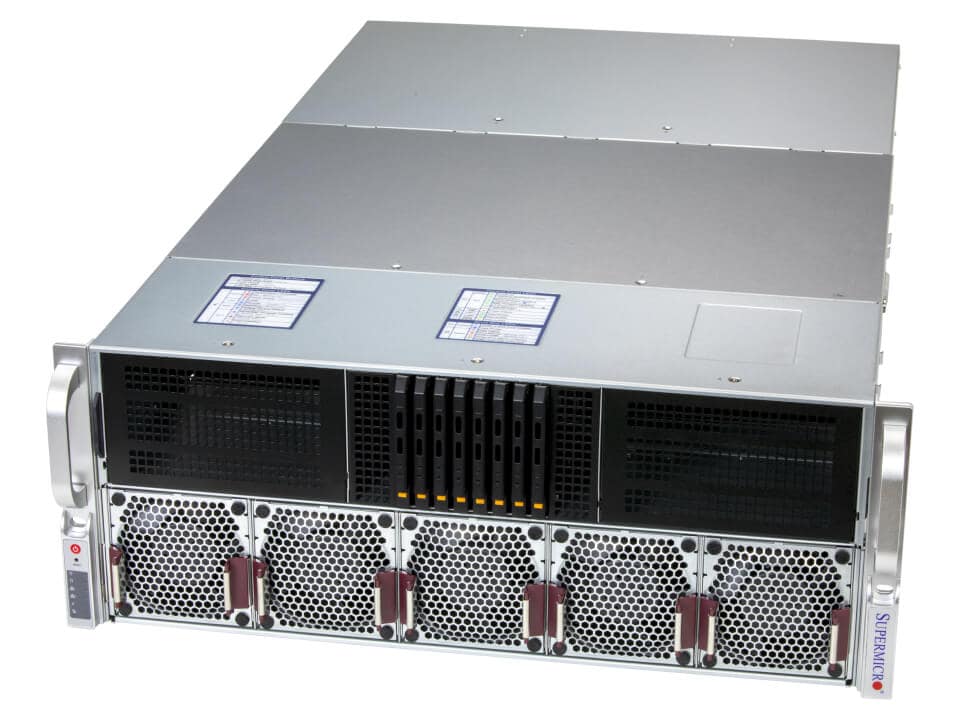
Eight PCIe GPUs in two NVLink domains of four GPUs each. Server and bridge compatibility is confirmed in the quotation.
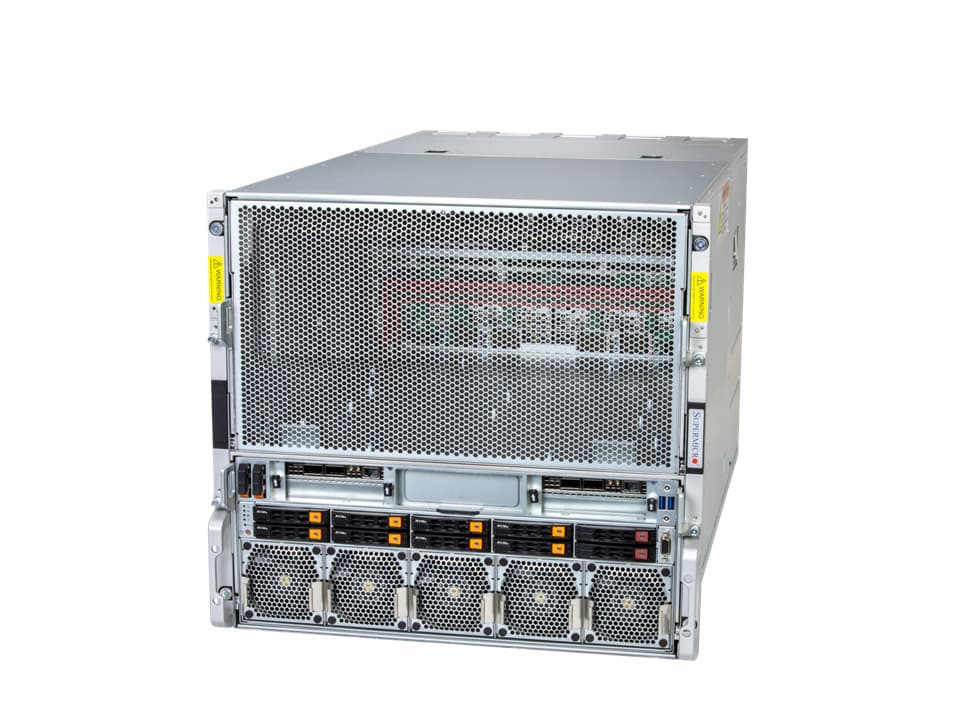
Eight MI355X GPUs. Cooling, power limits and site requirements depend on the server and are agreed in the quotation.
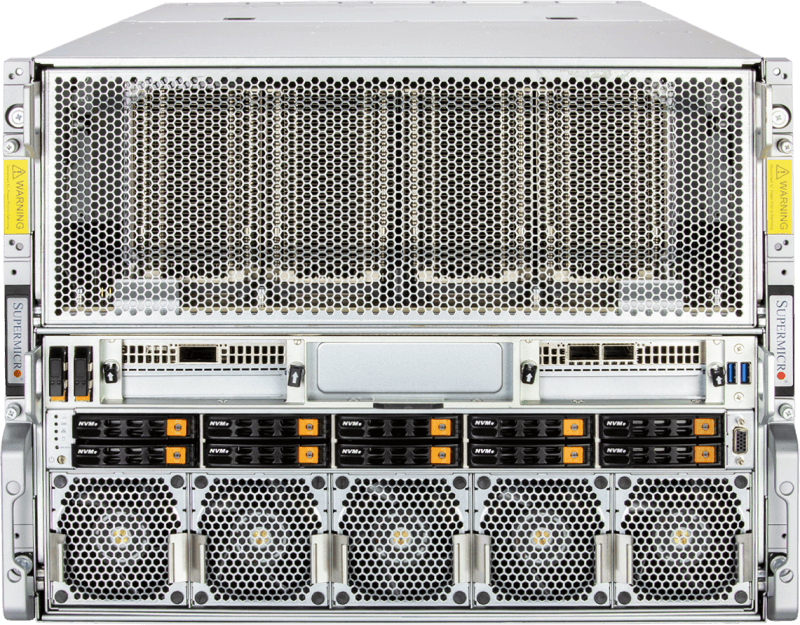
Eight accelerators for memory-intensive workloads.
Images show examples of complete systems for each platform. The exact chassis, installed accelerator count and configuration are confirmed in the quotation.
Prices are budget estimates, not binding offers or confirmation of stock. VAT, exact specifications, delivery, warranty and lead time are set out in the quotation. Accelerator memory is a total; usable capacity depends on software and interconnect topology.
Choose a model. Compare memory and cost.
| Platform | Memory | Memory fit | Discuss this setup |
|---|---|---|---|
| H200 NVL · 8 GPUNVIDIA · CUDAfrom $469,168 | 1,128 GB | Capacity fitsremaining 244.4 GB | |
| HGX H200 · 8 GPUNVIDIA · CUDAfrom $404,504 | 1,128 GB | Capacity fitsremaining 244.4 GB | |
| HGX B200 · 8 GPUNVIDIA · CUDAfrom $480,285 | 1,440 GB | Capacity fitsremaining 556.4 GB | |
| Instinct MI300X · 8 GPUAMD · ROCmfrom $356,168 | 1,536 GB | Capacity fitsremaining 652.4 GB | |
| Instinct MI325X · 8 GPUAMD · ROCmRequest a quote | 2,048 GB | Capacity fitsremaining 1,164.4 GB | |
| HGX B300 · 8 GPUNVIDIA · CUDAfrom $634,046 | 2,160 GB | Capacity fitsremaining 1,276.4 GB |
Nominal memory indicates capacity. Configuration, software, topology and availability require separate validation.
Source check:753 B — checkpoint parameters. 39 B — active per token.
Published checkpoint: FP8 / BF16 / F32. Weight payload from the published checkpoint or official deployment guide. This is stored payload, not measured GPU allocation; runtime conversion can increase it. Operating reserve is added separately.
Weight format: Start with the published checkpoint. Extra quantization may affect quality; converting quantized weights to BF16 does not restore lost precision.
Operating reserve: Memory beyond weights for KV cache, activations, runtime buffers and headroom across the selected configuration, not per GPU. Set it from context length and concurrent requests, then measure peak use. The presets are examples, not universal recommendations.
Model card ↗Published weight payload ↗Published deployment guide ↗This is the limit declared in the model configuration, not a context verified on the selected hardware.
DSA uses kv_lora_rank=512 and full/shared indexer types. Cache sizing requires an architecture-specific calculation.
Model config ↗Context config checked: .
Runtime validation required. Published deployment guide: HGX H200 · 8 GPU, Instinct MI355X · 8 GPU, Instinct MI325X · 8 GPU, Instinct MI300X · 8 GPU.
Weights = total parameters × bytes per parameter: BF16 2, FP8 1, INT4 0.5. Decimal GB. MoE models count every expert, not only active parameters. This is a lower bound: quantization scales, unquantized layers and metadata are not separately modelled; they must fit within the reserve.
A green result is a capacity estimate, not a tested deployment. GPU memory is distributed across devices. Tensor and expert parallelism, interconnects, model kernels and framework support must all be checked. Long context and parallel users can need much more reserve. Fine-tuning and training require a separate calculation.
KV cache depends on context length, concurrent requests, cache precision and the model’s attention architecture. Sliding-window, linear-attention and compressed-cache models need architecture-specific estimates; validate the peak in the selected runtime. This field changes the capacity estimate, not server settings.
Hugging Face: KV cache strategies ↗vLLM: Hybrid cache allocation ↗BF16 / FP8 / INT4 are size scenarios. The format names do not assert native execution support or equal model quality.
NVL topology and sharding require separate validation; an 8-GPU PCIe server is not the same fabric as HGX/NVSwitch. Validate the exact checkpoint and kernels in ROCm before deployment.
Huawei Ascend uses CANN. Capacity results do not confirm that the selected checkpoint, operators or precision run on these stacks. A model port and runtime validation are required.
The calculation uses 270 GB per GPU for HGX B300 and 279 GB per GPU for GB300, following the NVIDIA datasheet. The 288 GB figure is not used. CPU RAM is not added to GPU memory. NVIDIA Blackwell Ultra (PDF) ↗
Open weights do not mean unrestricted use. Read each model license and published deployment guide.
Let’s define a dedicated configuration for your workload. Rental term, hosting, access and support are agreed before launch.
Get a rental quote↗From the first specification to equipment handover. We work with companies in Kazakhstan and select infrastructure for their workloads.
Model, precision, memory, user count and performance targets.
NVIDIA, AMD or Huawei. We compare memory, accelerator interconnects, software compatibility and total cost of ownership.
Specifications, hardware checks, contract, invoice payment and warranty terms.
OMNAR is a Kazakhstan-based GPU server supplier. We select equipment for companies in Kazakhstan and prepare purchase and dedicated rental proposals.
A Kazakhstan legal entity, quotations in tenge and payment against an invoice.
Equipment, delivery, taxes and additional services are itemised in the quotation.
A server at your facility or a dedicated rental with agreed hosting and access.
Three starting points for planning your infrastructure.
Define the model, context length, concurrent users and acceptable response time.
What to prepareDescribe the data, fine-tuning methods and run duration. Compare buying and renting for the same workload.
What to prepareCheck the site, power, cooling and network before committing to servers or a full rack.
What to prepareFrom the first memory estimate to server acceptance, the detail lives in dedicated guides.
The workload, operating requirements and acceptance evidence needed to compare proposals before placing an order.
Read the guide: How to write a GPU server specificationSeparate weights, KV cache and operating headroom, account for MoE, and validate the estimate against a real workload.
Read the guide: How much GPU memory does a language model need?Compare both options against one workload: utilisation, duration, control and the complete cost.
Read the guide: Buy or rent a GPU serverFrom rack space and power to access, software versions and acceptance: agree the essentials before delivery.
Read the guide: Prepare your site for a GPU serverTell us about your model and expected workload. Send a server purchase or rental enquiry with the details we need to prepare a quotation.
Start with your model and software stack: CUDA for NVIDIA, ROCm for AMD and CANN for Huawei. Then verify weight formats, memory placement and performance on your workload. Equal memory capacity does not make platforms interchangeable.
Pricing depends on the configuration and delivery terms. Request a quotation with the final price in KZT, VAT details, delivery lead time and warranty. Availability is confirmed in the quotation.
HGX H200 uses an SXM platform with NVSwitch. A PCIe build with H200 NVL needs compatibility checks and may consist of two groups of four GPUs. This is not equivalent to the eight-GPU HGX interconnect fabric.
Configuration, term, data center, connectivity, access and support are agreed individually. Capacity and start dates must be confirmed; instant provisioning is not promised.